"The scale math makes this a correctness and fairness problem, not a throughput problem: even at peak, every waiting room fits in one process's memory. So the truth lives in Postgres, one single-threaded matcher owns each (game, region) room, a guarded compare-and-set referees every claim, and a 5-minute deadline wall is enforced by machinery, not hope."
Requirements
4 minFour questions. State your assumption for each so the interview moves even without answers.
- What is "skill" and who owns it? Assume a 0-100 number from an external skill API, fetched once at join and snapshotted. The matcher never calls it.
- How big is a match? Assume per-game config: K players, 2 to 10, and K includes the anchor. Bots may fill empty seats where the game allows.
- Is the 5 minutes a hard promise? Assume yes: the game starts by the deadline even if match quality is not ideal, and the deadline is stamped at join and never moves.
- How strict is join order? Assume roughly join order and nobody waits forever. Players can cancel while waiting and must hear about their match the moment it forms.
- Out of scope, say it: running the game session (we ask that system for a server address and hand off), computing the skill number (the skill API owns it), and party queues (worth one sentence as an extension if asked).
1M daily users × ~5 games/day ≈ 60 joins/sec average, 300-600/sec at peak (5-10x factor). Waiting population = arrival rate × average wait: at peak with a 30-60s wait, 10-40K people waiting. A couple hundred bytes each, so a few MB total: every room fits in one process's memory. 100K games, but maybe a thousand have an active room at any moment.
A match request ends in exactly one outcome: one match, or a cancel. Two matches claiming the same player is the disaster case. Players hear about a match within a second or two (one 500ms tick + the server-allocation call + one push). Postgres is the one hard dependency: it runs with a SYNCHRONOUS standby, which these tiny write volumes easily afford, so a failover can never un-commit a match a player was already told about.
Core entities
1 min- Match request: one waiting player. Skill snapshot (plus an estimated flag if the API was down), joined-at, a hard deadline of join time + 5 minutes, status WAITING → MATCHED or CANCELLED, and the match id once matched.
- Match: the formed group. Which game, which players, how far apart their skills ended up, and whether it formed normally (FILLED) or because time ran out (TIMEOUT). Timed-out players still become MATCHED; the TIMEOUT tag lives on the match, not the player.
- Game config: how many players a match needs (K, 2 to 10, includes the anchor), how fast the skill window widens, and whether bots may fill seats. 100K games get a global default curve with per-game overrides.
- Skill: fetched from the external skill API once, at join, and saved on the request. External answers get recorded at the boundary, not re-asked in a loop.
API
3 min
POST   /v1/games/{gameId}/queue     { region }   // region = where the player is; we match nearby first
  → 202 { requestId, skillSnapshot, deadline }   // deadline is stamped now and never moves
  → 409, body: { error: ALREADY_QUEUED, requestId }   // unique index on (userId, gameId) where status=WAITING; a retry gets the existing id back
GET    /v1/queue/{requestId}                        // polling fallback for status
WS     /v1/ws                                       // push: MATCHED { matchId, serverAddr }
DELETE /v1/queue/{requestId}                        // cancel; 200 while WAITING; 409 ALREADY_MATCHED or ALREADY_CANCELLED
PUT    /v1/queue/{requestId}/heartbeat              // stop sending these and we cancel you
- 202, not 201: joining starts a process rather than creating a finished thing. The real answer arrives later, over the socket.
- There is only one push type. A timed-out start is still a MATCHED push, because a timeout still forms a real match with a real server address.
- The 409 on cancel exists because a cancel can race the match forming. Dive B covers who wins.
High-level design
10 min, end to end, no dives yetplayer → API → skill API snapshot (300ms timeout, estimated flag) → match_requests in POSTGRES (truth) -- row 1: the door one MATCHER per (game, region): 500ms tick, oldest anchor, widening window → guarded claim txn: match + K players + outbox -- row 2: the loop outbox → server allocation (key = matchId) → pub/sub by user → gateway WebSocket push; deadline wall checked every tick -- row 3: the promise
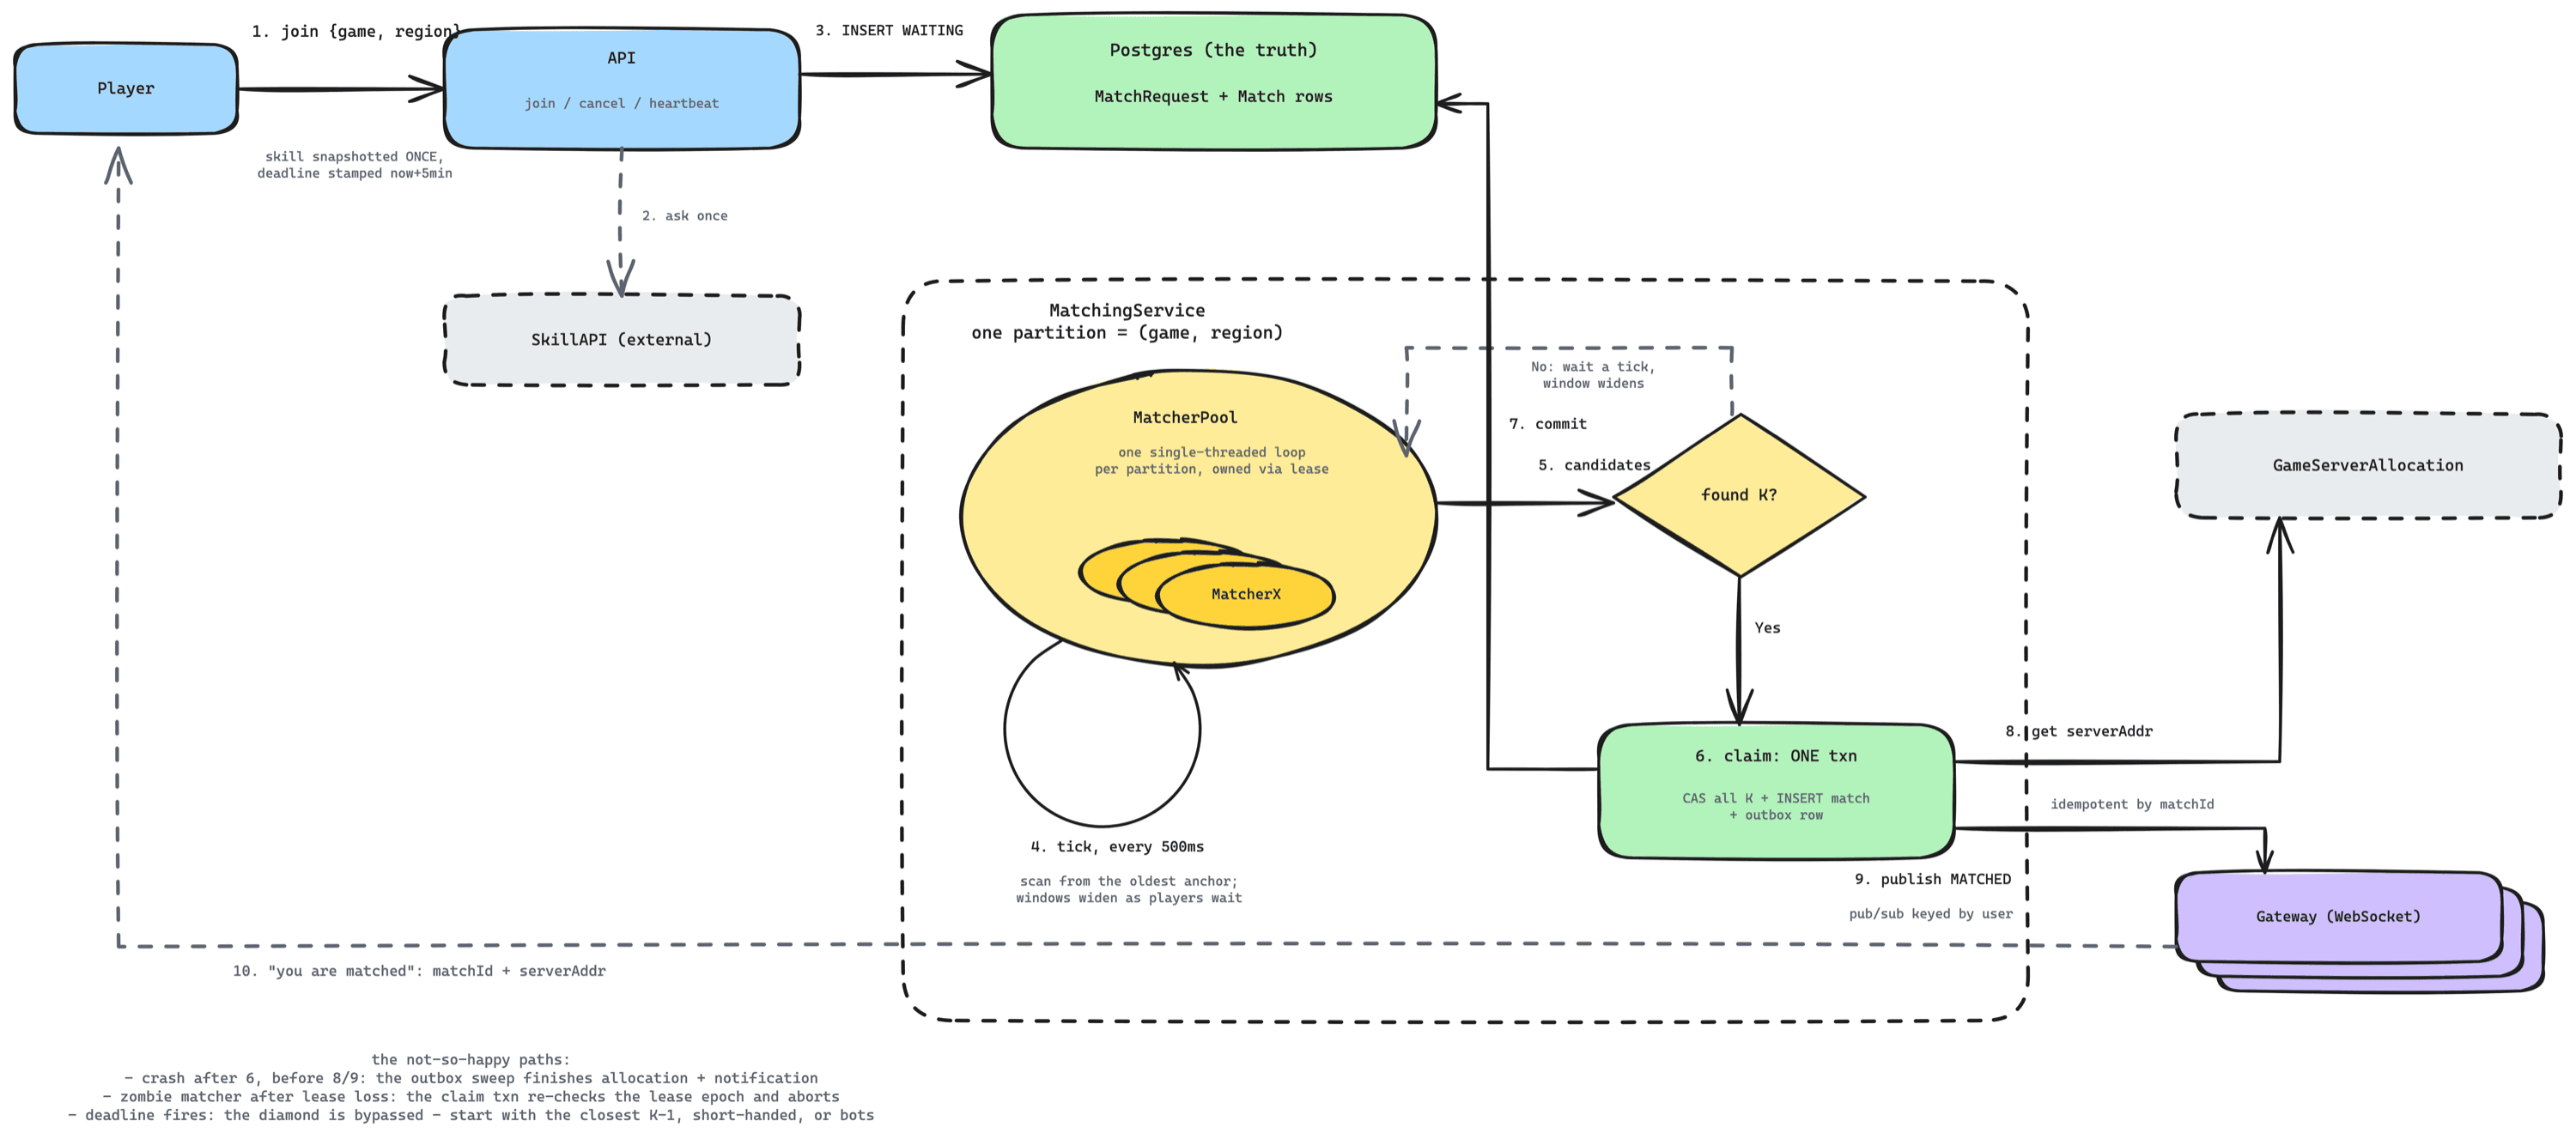
Joining writes the truth first: the API asks the skill API once with a 300ms timeout (down OR slow, same fallback: last known skill or 50, estimated flag set, so availability and join latency never degrade), stamps the hard deadline, and inserts the request as WAITING in Postgres before the player sees their 202. One single-threaded matcher owns each (game, region) room in memory; joins, cancels, and heartbeats reach it as messages, and every 500ms it matches from the oldest player outward with a skill window that widens as they wait → dive C. When it finds K, it claims match, players, and an outbox row in one guarded commit → dive B; the matcher then allocates a server on the critical path and publishes the MATCHED push, with the outbox row as the backstop, so a crash after commit still finishes → dive D. The soonest-deadline check every tick is what makes the 5-minute promise real: when the wall hits, the window no longer applies, and the game starts short-handed or with bots if the game allows, recorded as TIMEOUT.
- Start from the player waiting longest: the anchor. Their acceptable range grows with age: roughly ±5 just joined, ±15 after a minute, ±30 after three, anything goes as the deadline approaches.
- An estimated-skill player starts at ±15, because pretending we know an estimated number to ±5 would manufacture bad matches.
- Walk the queue in join order, collecting players inside the anchor's range, until K including the anchor.
- Coherence check: also drop a candidate whose distance from the players already collected exceeds the window, so two teammates cannot be twice the window apart.
- The window is one-sided, and that is a choice: admission is judged by the anchor's widened range, so a fresh player can be pulled into a wide match sooner than their own young window would allow. We accept that because it rescues long-waiting players faster; a stricter variant also checks the candidate's own window and pays with longer waits.
- If the anchor cannot match this tick, do NOT stop: try the next-oldest as anchor, bounded depth (say the 10 oldest). A lone skill-5 outlier at the head must not block six skill-90 players behind them.
- The outlier is not abandoned: their window keeps widening, and their deadline is absolute. Age buys reach; the wall catches whoever reach never helped.
- Cancel and match are both a compare-and-set on the same WAITING status; whoever commits first wins. The cancel API does the CAS synchronously (200 or 409 immediately), then messages the matcher so the in-memory queue evicts that player rather than anchoring on a ghost.
- The matcher does not hold sockets: it publishes MATCHED to a pub/sub channel keyed by user, and whichever gateway holds that socket delivers it. Gateway restarted: the client reconnects and the GET status endpoint catches it up. A duplicate push is harmless because it carries the same match id. Polling is the fallback for everything.
- If they just nod and wait: "the riskiest part is the claim transaction, shall I open exactly-one-match?"
- Running behind: protect dives B and D. Dive E exists for the goalpost move to 100K QPS; do not open it unprompted.
Deep dives: the core four
~20 min, interviewer steers- Two writers reach for the same WAITING player: a stale matcher during a lease handover, or a cancel racing a claim. Adjacent-region matching (dive A) adds one more way for two rooms to want the same player.
- The naive design, many matcher threads scanning a shared table with no referee, ends with two matches claiming one player: one match starts a player short, and nobody can explain why.
BEGIN;
SELECT 1 FROM leases WHERE partition=$p AND epoch=$my_epoch FOR SHARE;
-- zero rows means we are a zombie: ROLLBACK. Takeover bumps the epoch with an
-- UPDATE, which conflicts with this FOR SHARE, so a stale owner cannot slip through.
INSERT INTO matches (id, game_id, players, formed_by) VALUES (...);
UPDATE match_requests SET status='MATCHED', match_id=$1
  WHERE id IN ($2...$k+1) AND status='WAITING';
-- row count must equal K, or ROLLBACK and retry without the missing player
INSERT INTO match_outbox (match_id) VALUES ($1);
COMMIT;
- One transaction creates the match, claims all K players, and records an outbox entry saying "this match still needs a server and notifications".
- If someone cancelled meanwhile, the row count comes back short of K, and the whole transaction rolls back.
- Give each (game, region) exactly one single-threaded matcher: match forming, cancels, and timeouts all become messages into one loop, so in steady state there is nobody to race. Affordable because one room fits in memory, and matching wants to scan a queue, which a single owner does naturally.
- The competing-matchers alternative: SELECT ... WHERE status='WAITING' ORDER BY joined_at FOR UPDATE SKIP LOCKED, then claim. Name its cost before they do: skipping locked rows quietly abandons strict join order, the exact fairness this design is built on.
- Be precise about which mechanism does what: the guarded UPDATE is the correctness mechanism; the single writer is a contention and simplicity optimization. A paused-then-waking zombie matcher, or an adjacent region reaching for your player, still exists; the CAS stops them, and the lease epoch makes a stale owner's claims recognizably stale.
- A strict skill window makes great matches and broken promises; a loose one keeps the promise while ruining the matches. A fixed window (say ±10 forever) fails at quiet hours: nobody is within 10, so players sit there until the deadline surprises everyone.
- Everyone starts picky and gets less picky: quality when the room is busy, certainty when it is not.
- Drive each tick from the oldest matchable player, whose window is widest, and enforce the deadline separately with the soonest-deadline check. Order and widening become one mechanism; the promise never depends on the window.
- A periodic batch optimizer: every few seconds, assign the whole pool to matches minimizing total skill spread subject to wait limits. It fixes greedy's blind spots (head-of-line waste, first-K instead of closest-K).
- Decline it with reasons: K is small, rooms are small, strict join order is a stated requirement, and greedy with widening plus multi-anchor retry approximates it well at this scale. For team games with roles, revisit that choice.
- Watch one number: the fraction of matches that formed by timeout. If it climbs, the window curve is too strict or the game's population is too thin.
- That metric, alongside p95 wait and per-match skill spread, drives every tuning conversation.
- The memory-only version silently unqueues thousands of people on a crash; they wait forever for a match nobody is building.
- Instead, every join was written to the table before the player got their 202, so a restarted matcher rebuilds its room by reading the WAITING rows. The claim transaction committed everything or nothing, so the queue cannot be half-claimed.
- A matcher owns its partition through a lease row in Postgres with an epoch number. Process dies: the lease expires, a peer takes the partition at the next epoch and rebuilds from the table. Nobody is lost, and a zombie's stale epoch is refused.
- A match can commit and the matcher can die before allocating a server or notifying anyone, leaving K players MATCHED with no game. That is why the claim writes an outbox row.
- The takeover matcher sweeps unprocessed outbox entries, finishes the allocation call, and re-sends the notifications.
- Both repeats are safe because each carries the match id: the allocation call uses it as an idempotency key (asking twice returns the same server), and a duplicate push is ignored by the client.
- Heartbeats flow to the matcher and live in memory, NOT written to Postgres per beat: 40K waiters beating every 10 seconds would be 4K writes/sec, dwarfing the 60-600 joins/sec we sized for. On takeover, everyone gets a fresh grace period.
- When the beats stop, the matcher cancels that player with the same CAS as a user cancel. The point is to evict them BEFORE a match forms around them, so K-1 real players never start a game with a ghost teammate.
- 100K joins/sec is a different planet from our 300-600 peak. Waiting population = arrival × wait: 100K/s × 30-60s = 3-6M players waiting. Their state is still only about 1GB in aggregate, so memory is not the problem. Write throughput is.
- Hunt for the biggest number first: it is not joins. 3-6M waiters heartbeating every 10s is 300-600K heartbeats/sec, three to six times the join rate. Dive D already keeps heartbeats out of Postgres; at this scale that decision stops being a nicety and becomes the design: the biggest flow never touches the database. What remains is to carry it through the front door and size every tier for it.
- Downstream, with K=5: about 20K matches/sec, so 20K server allocations/sec, 100K MATCHED pushes/sec, 3-6M concurrent WebSockets that all want an answer within a second or two.
- Say it out loud: the problem was correctness at small scale; now it is correctness AND throughput, and the win condition is keeping the exactly-one-outcome machinery while spreading the writes.
- Replicas absorb reads, but this workload is writes: 100K join inserts, ~20K claim transactions touching K rows each, plus cancels, every second, all on one primary and its one WAL. A single well-tuned primary tops out somewhere in the tens of thousands of small transactions per second: past the wall even with heartbeats already kept out.
- The synchronous standby we rightly insisted on adds a network round trip to every commit, so the latency floor rises exactly when the volume explodes. And vertical scaling leaves one blast radius: when that primary fails over, every waiting room in the world stalls at once.
- Shard Postgres by hash of (game, region), the same key the matchers partition on. The load-bearing observation: outside the adjacent-region case, all K players of a match live in the same (game, region) partition, so the guarded claim stays single-shard. The CAS referee survives sharding untouched.
- With 64 shards, each sees roughly 1.6K inserts/sec plus a few hundred claim transactions, comfortable for a primary with a synchronous standby, and a failover now stalls 1/64th of the world instead of all of it.
- The outbox and its sweeper go per-shard; pub/sub shards by userId. The one cross-shard case is the adjacent-region hand-off (dive A): keep it an ownership hand-off and form the rare cross-region match as two single-shard steps driven by the outbox (reserve the player at home, then form the match), never a distributed transaction. The reserve step is the same guarded CAS with the forming matchId stamped, so a crash between the steps is the familiar outbox-crash story: the sweeper finishes the match or frees the player.
- API tier: count the real ingress: 100K joins + 300-600K heartbeats + cancels is 400-700K req/sec, and heartbeats are most of it. The staff move: take heartbeats off HTTP entirely. 3-6M players already hold WebSockets, so liveness rides the socket's ping/pong at the gateway for free, and the API tier sizes for the remaining ~100K rps, about 100 nodes at 1K each. Heartbeats stay in matcher memory, never Postgres; if someone suggests persisting liveness for the failover case, the takeover grace period from dive D already covers it.
- Skill API: once per join is now 100K reads/sec against someone else's service. Snapshot-once already saved us from polling; add a short-TTL read-through cache, batch the lookups, keep the estimated-skill fallback.
- Join ingestion: joins fan into rooms through a partitioned log keyed by (game, region). The log is transport, not truth: failover recovery still rebuilds the room from the table, exactly as dive D says.
- Matchers: the model does not change, one single-threaded loop per room. ~10K active rooms, averaging 10 joins/sec per room, which is nothing. Raw heartbeats would be the real message load (a viral room with half a million waiters would take tens of thousands of beats/sec into one loop), so gateways aggregate liveness into a per-room digest every few seconds and the loop consumes digests, not beats. The viral-room math does change: at 10K joins/sec one room holds 300-600K waiting players; the per-tick work is the oldest anchor's window scan, not a full pass over the room, and if that scan ever stops fitting the 500ms tick, the room splits into skill bands with FIFO inside each band.
- Gateways: 3-6M sockets at ~50K per node is 60-120 nodes. The failure that matters is the reconnect storm after an AZ loss: reconnects carry jitter and a resume token, and a reconnect never re-joins a queue, it re-attaches to an existing requestId.
- Allocation: 20K matches/sec against a pre-warmed server pool. While the pool has headroom the call stays on the critical path for latency; when it runs dry, the outbox absorbs the burst and notification lags instead of matches failing.
- Bulkheads and alarms: a degraded shard 503s joins for its own rooms and touches nothing else; the alarm is per-room p99 time-to-match against the 5-minute wall, not a global average that hides one dying shard.
- Survived: exactly one outcome per request (single writer plus CAS, now per shard), the 5-minute wall, and join-order fairness, which was always per-room anyway.
- Traded: no single place to query the whole world, so global reporting becomes an async rollup, and cross-region matches form in two steps instead of one transaction.
Three more dives
rehearse after the core four- Region is part of the partition key, so matching starts local.
- When a player has waited long enough, their home matcher offers them to the adjacent region's matcher and keeps ownership (and the deadline) until an acknowledgement comes back; only then does the hand-off complete.
- A lost offer therefore costs nothing: the player simply stays home and the offer repeats next tick.
- The CAS referee backstops the brief window where both rooms know the player: this is one of the three races dive B names.
- Make matching distance a weighted sum of skill difference and activity difference, compared against the same widening threshold. One mechanism handles any number of dimensions.
- Give those players a head start on the queue clock, capped at about 30 seconds, and leave their 5-minute deadline untouched.
- The cap is the no-starvation argument, and the deadline index is what keeps the promise intact while the queue order bends.
- Check numbers before designing: even if one game somehow carried the entire system's peak of 600 events/sec, that is light work for one thread. If it ever truly breaks, split that one game's room into skill bands with FIFO inside each band.
- A player can queue for two different games at once and win both. If the product wants exclusivity, a MATCHED push triggers cancels of the player's other WAITING requests; if not, it is allowed and documented.
- A working queue, matcher, and timeout path, and knowing the skill API is asked once at join rather than polled during matching.
- Nail the exactly-one-match machinery: the guarded claim, the cancel race, the outbox for the post-commit crash. Truth in the table with memory as a cache. The widening window stated as an actual curve.
- Open with the scale math that turns this into a correctness problem. Name both alternatives (SKIP LOCKED fleets, batch optimization) and decline them with reasons. Spot head-of-line blocking in your own greedy design. Treat the timeout fraction as the product dial. Drive the exactly-one-match probe instead of waiting for it.
- And when the interviewer moves the goalposts to 100K QPS: redo the scale math, notice the biggest flow (heartbeats) already bypasses the database, and size every tier for it before adding hardware.
The five hardest probes
show all (interview mode)Read the Step 4 walkthrough aloud once, timing yourself. If it runs past 90 seconds, cut words until it fits. Then answer probe 1 from memory before opening it.